Academic Management and Legal AI Platform
Law went digital. Legal education didn't.
Why it matters — one system, four roles, the same objects and the same rules, without becoming four products.
Product Designer, end-to-end · AppX
May–Aug 2026 · 30+ high-fidelity prototypes
In implementation — no outcome data yet
The decision I'd defend — permissions as named, reusable groups with dependencies, not screen-by-screen configuration.
A system that absorbed what nobody planned for
LexKey is in implementation, so there's no measured impact. The funding paid for the build; whether institutions adopt it is the question still open.
What the design left in place is a shared grammar: permission groups with dependencies, specialised flows where the task demands them, and an AI that applies criteria written by people. When a fourth role appeared mid-build, that grammar held it without rebuilding anything.
That's the measure that matters to me. Not how many screens I drew, but how much of the unplanned the system absorbed.
Thanks to the AppX team, and to the lawyers who reviewed every rule.
The Problem
Law digitised fast. Teaching it didn't. Research happens in databases. Legislation is consulted in tools that show versions and cross-references. Students spend five years studying from PDFs and being assessed on paper, then enter a market where none of that is practised.
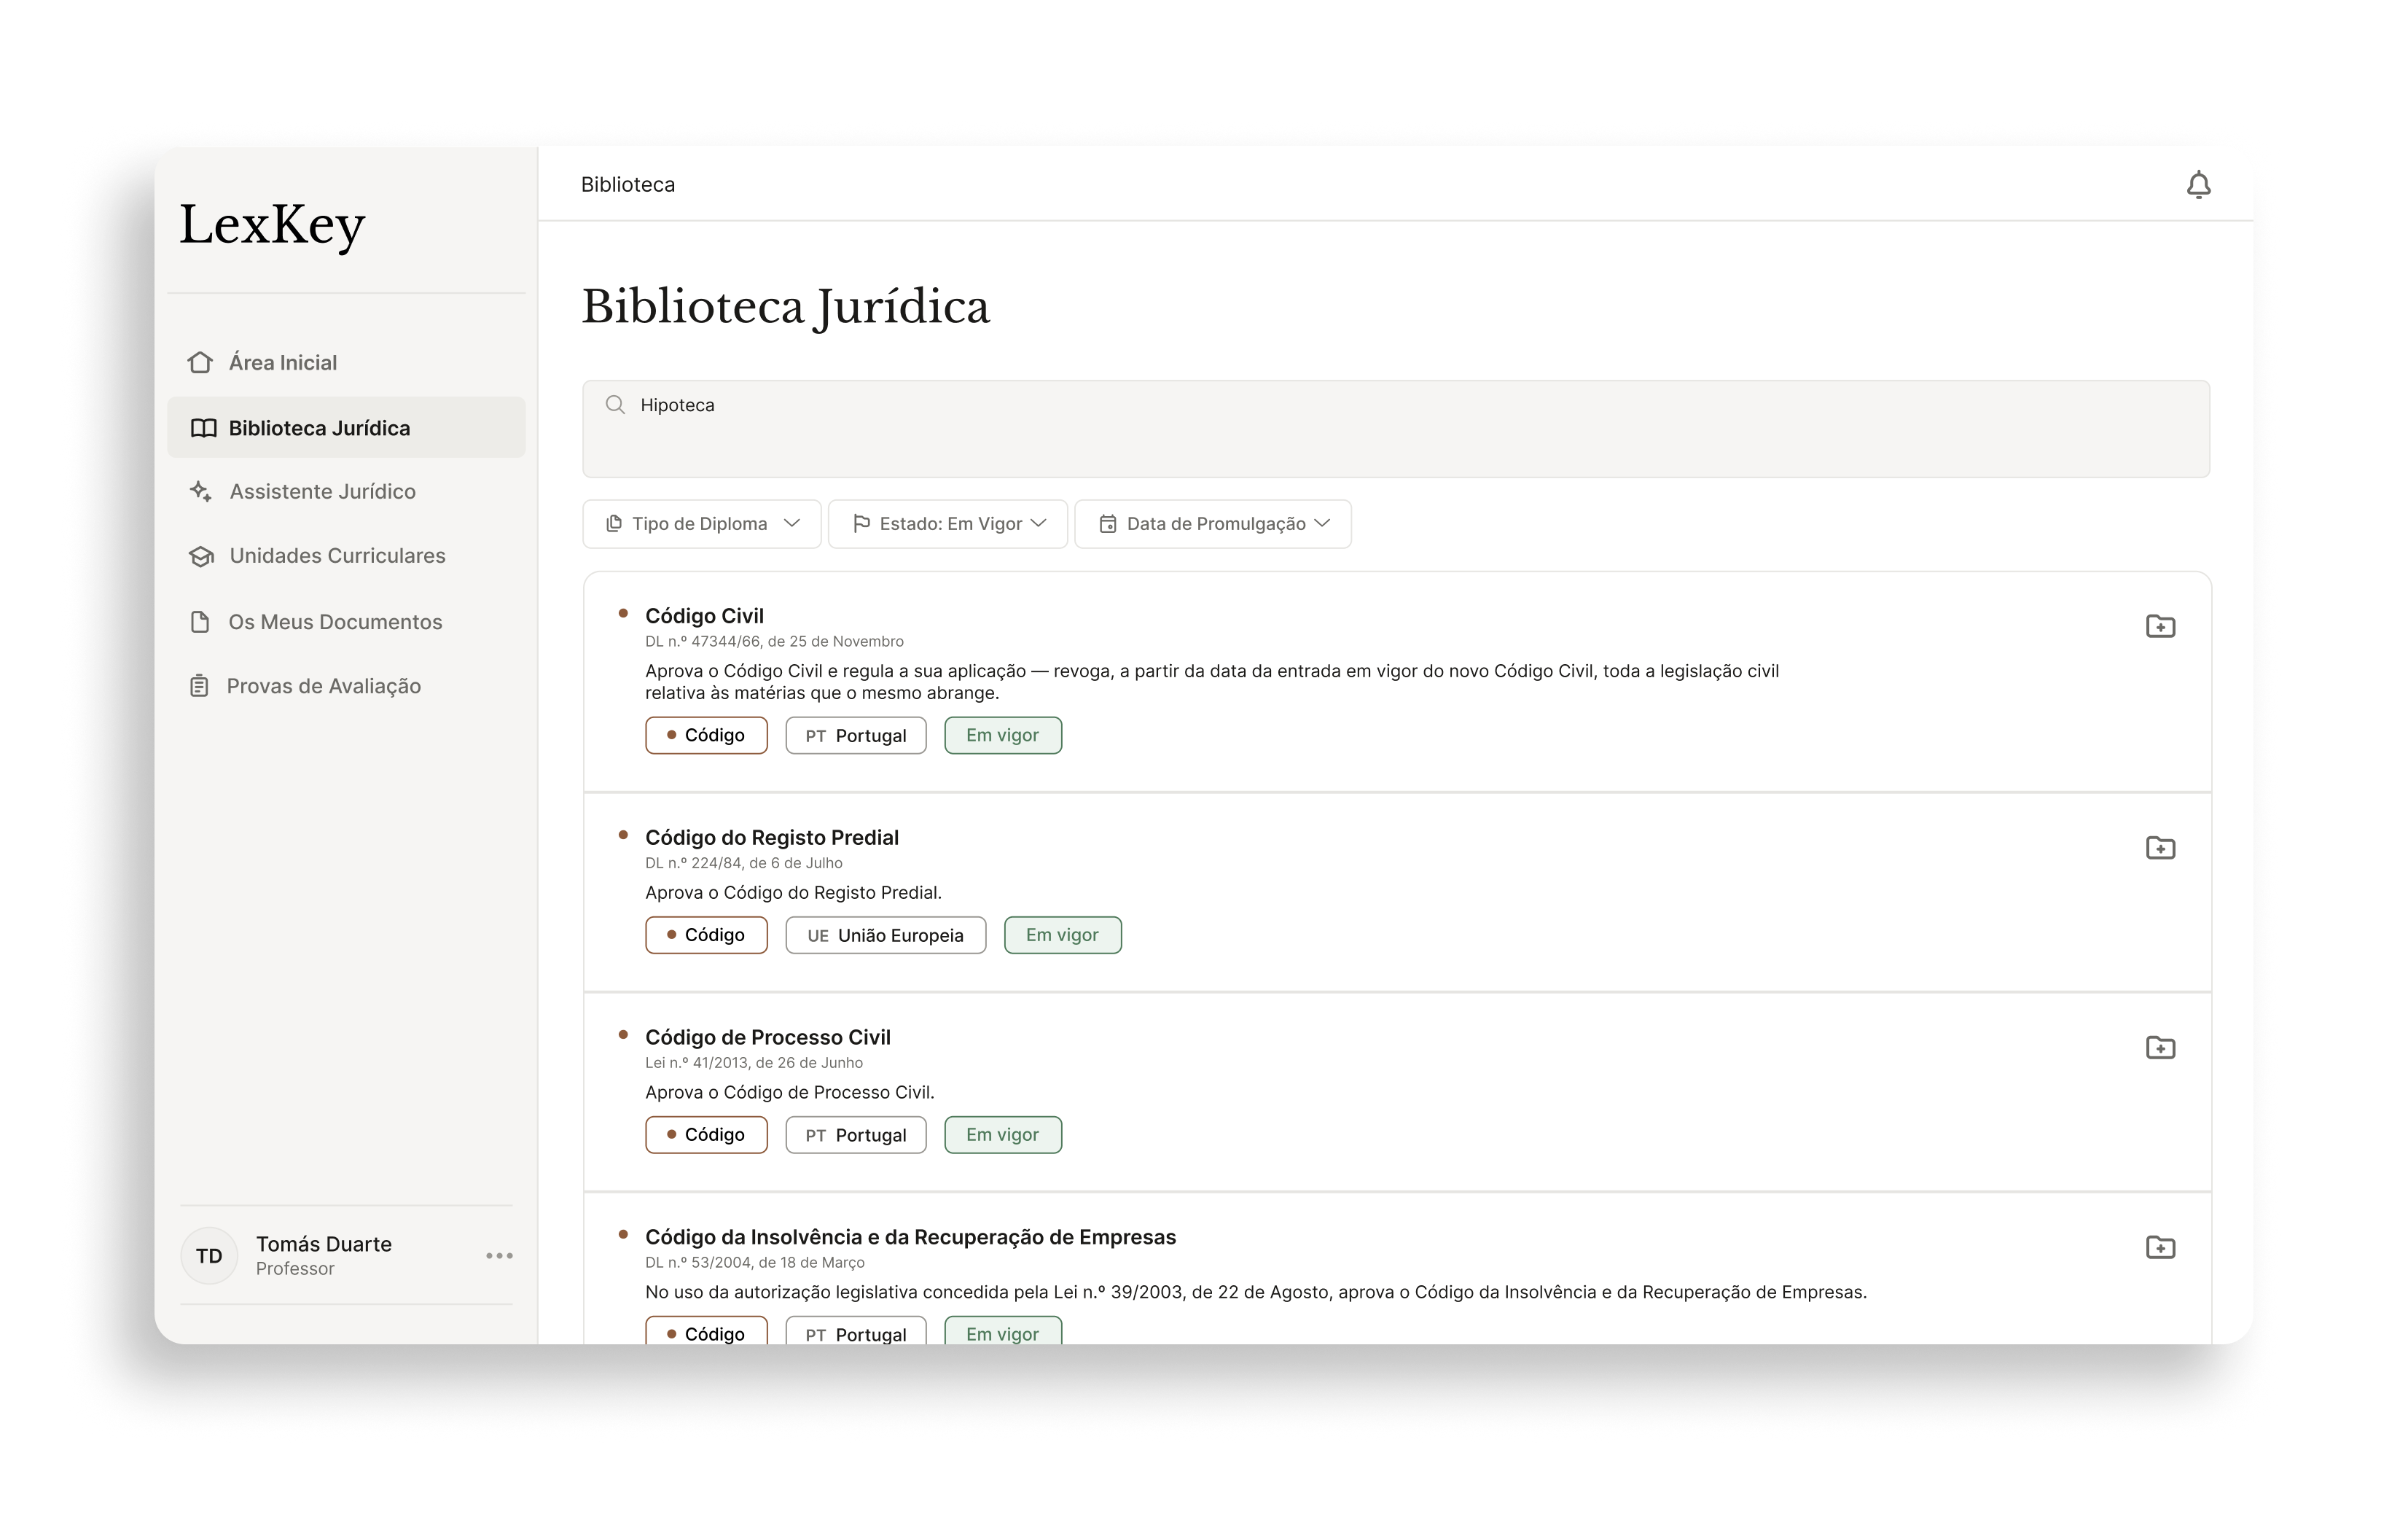
That makes the domain a design constraint, not content. Legislation has versions, states of force, cross-references and several types of instrument. All of it has to stay legible while someone works directly on the law.
Four roles, one object model. Admin, Institution Manager, Professor and Student share the same objects and the same rules. A class created by a Professor has to make sense to a Student. A permission set by an Institution Manager has to have predictable consequences elsewhere.
It's an institutional sale, not a consumer one. Several institutions run on one platform, with their users, contexts and permissions isolated from each other. Nobody signs up individually — adoption is decided once, by the institution. That's what makes the cost of standing up a new one a commercial number, not just a design one.
And the main adoption barrier wasn't another AI platform. It was the LMS institutions already had in place. We matched the LMS on academic management and differentiated on assessment and on working directly with the law — the two things an LMS was never built to do.
My Role
End-to-end Product Designer. I owned the design work; the product decisions were made by the team.
In practice I was usually the one framing the choice — bringing the alternatives, the trade-offs and a recommendation, then designing whatever the team landed on. Main flows for all four roles, dependency and edge-case modelling, the shared visual system, and a component-by-component handoff.
The fourth role is the clearest example of that contribution: I identified the gap and proposed the role. The team discussed it and the client approved it.
Built with IAPMEI recovery funding, which brought two conditions: a fixed deadline, and building from scratch rather than on top of an existing system.
The System
Permissions aren't a settings screen. They're the product's grammar.
Capabilities are grouped, named and reusable, with dependencies visible in the interface: switch off a parent capability and everything depending on it switches off and recedes.
The domain is structural, and the model had to match it. Law is organised by hierarchies, numbering and relations between articles. A flat list of permissions carried none of that — which is where the dependency structure came from.
The same grammar ended up solving two problems that looked unrelated: configuring an institution, and configuring an exam.

Decisions
A fourth role, added mid-build. The Admin had access to every institution, which meant any faculty's administrative task went through someone outside it. In a multi-tenant product, that doesn't scale. I raised it and proposed an Institution Manager. Design exposed the gap — the business model already assumed many institutions; the permission model didn't. It also became the best evidence for the group system: adding a whole role mid-development didn't force a permissions rebuild.
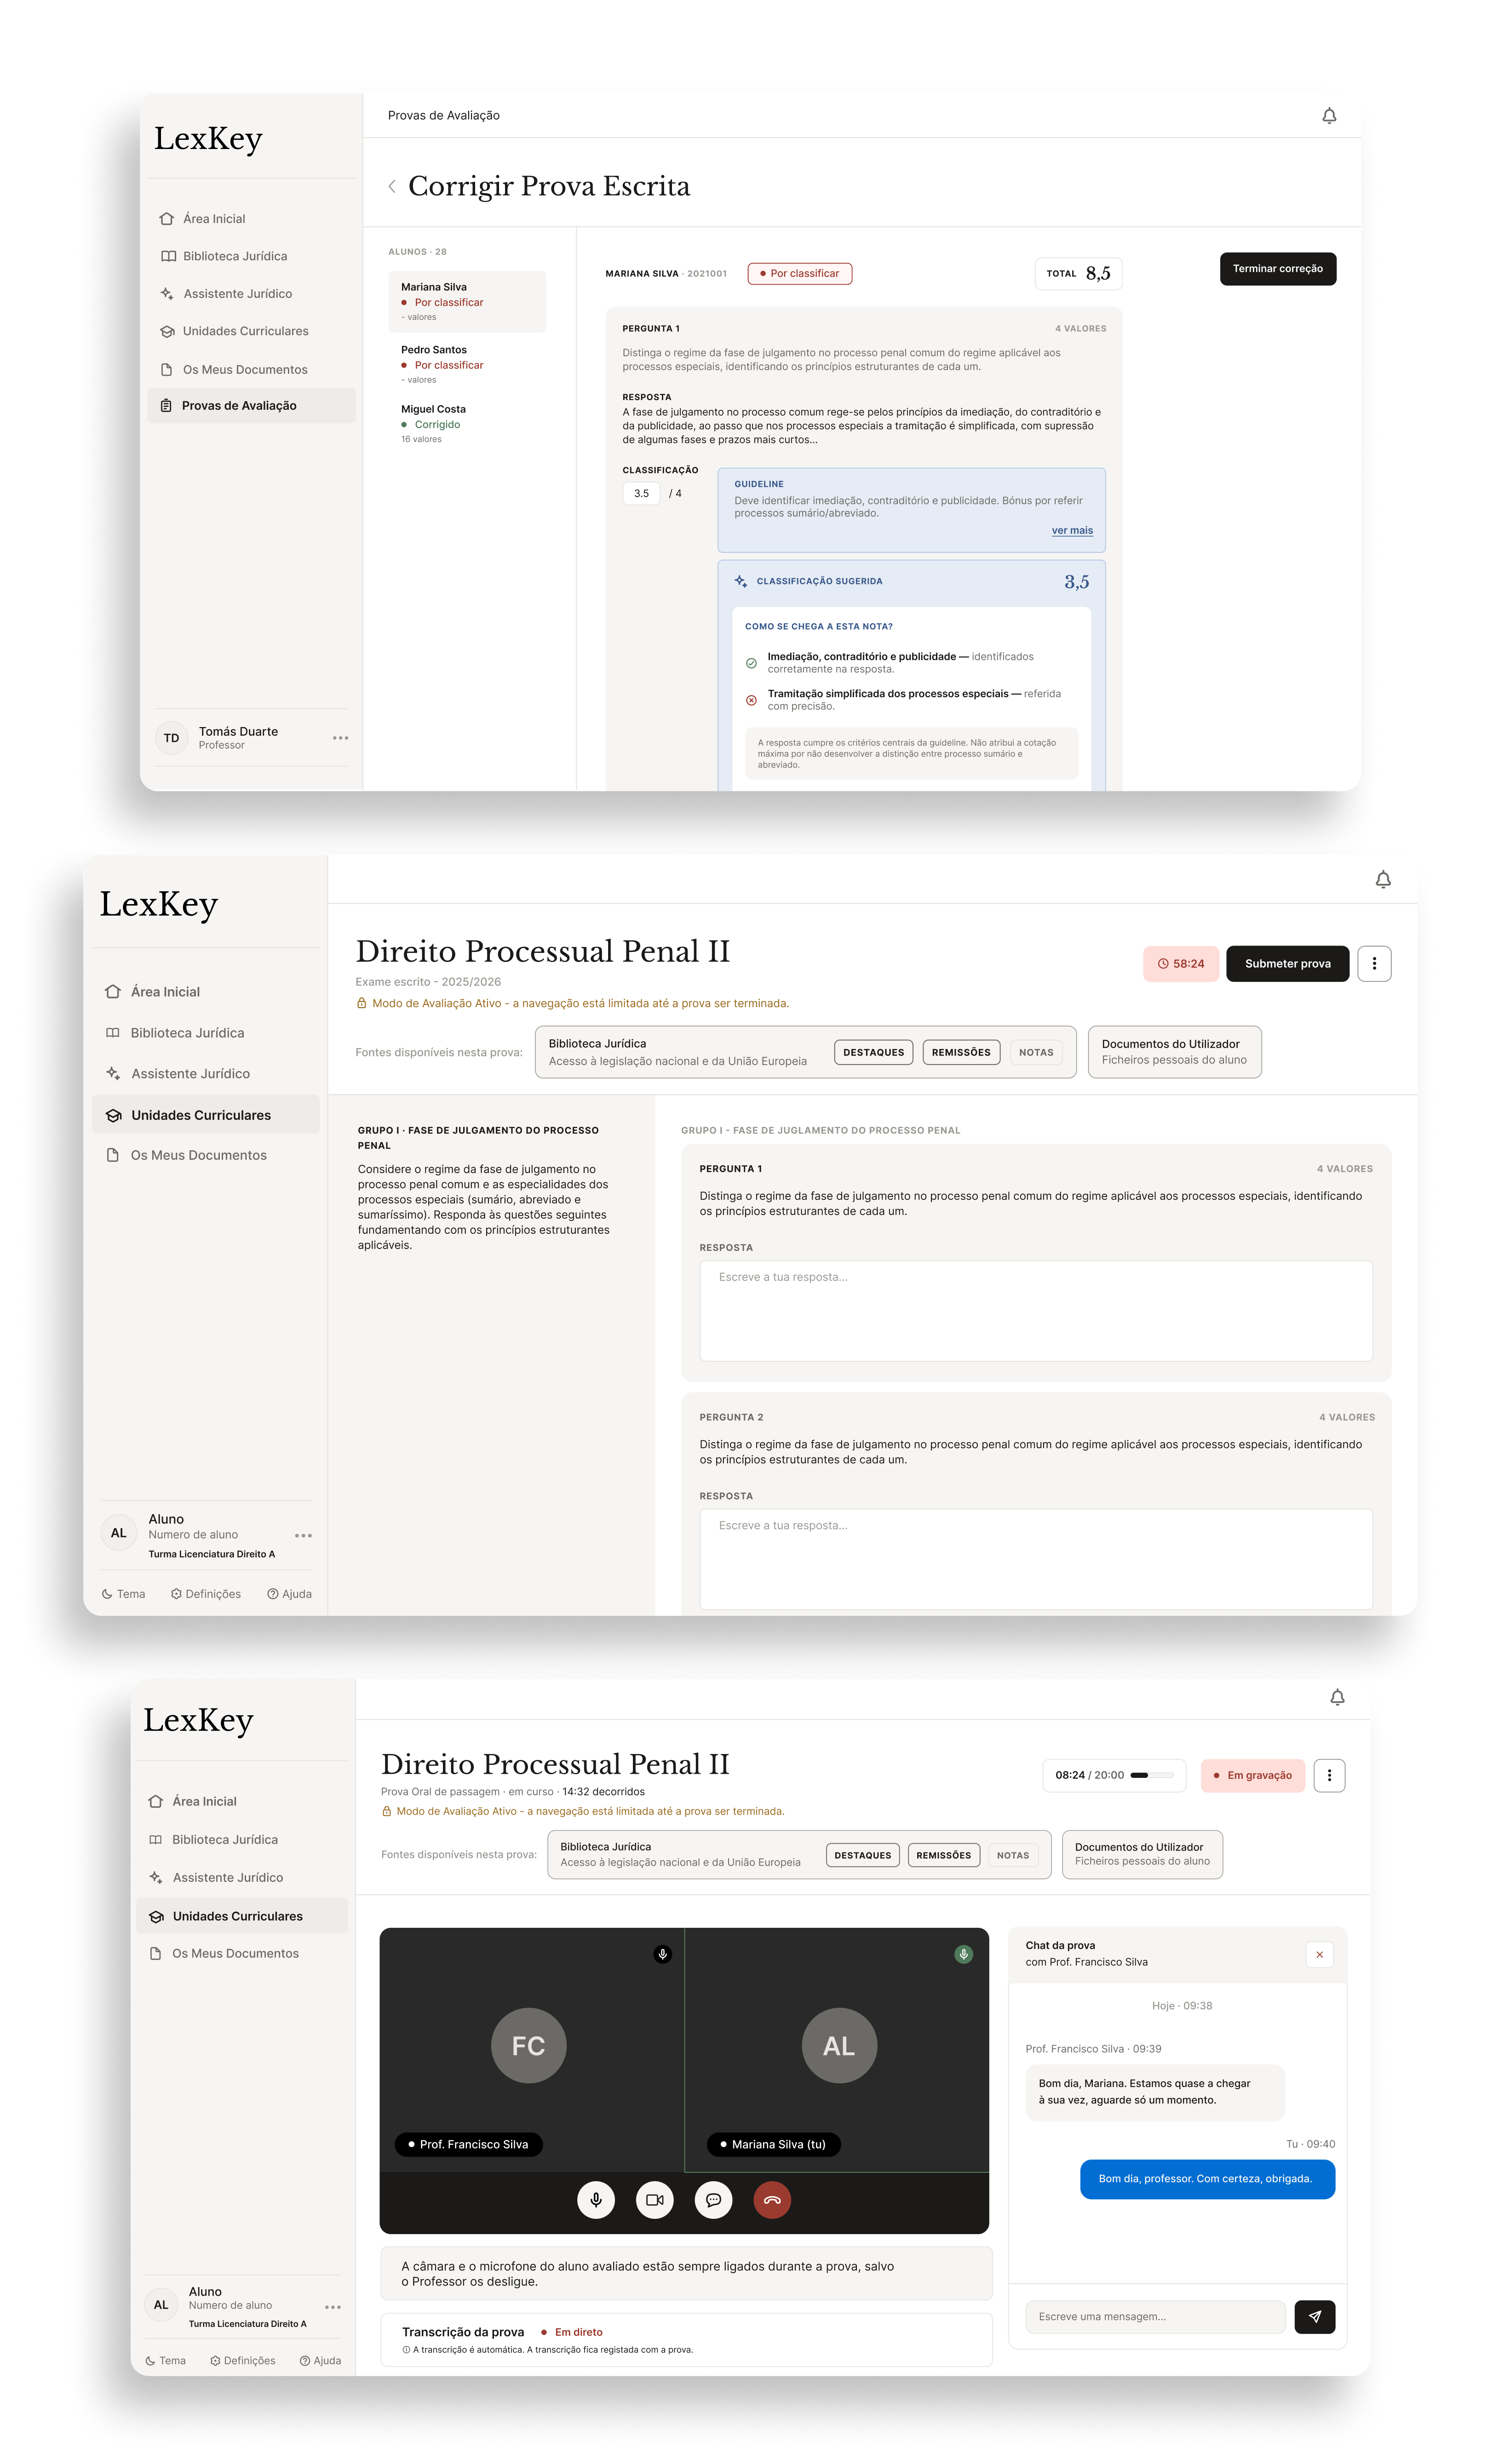
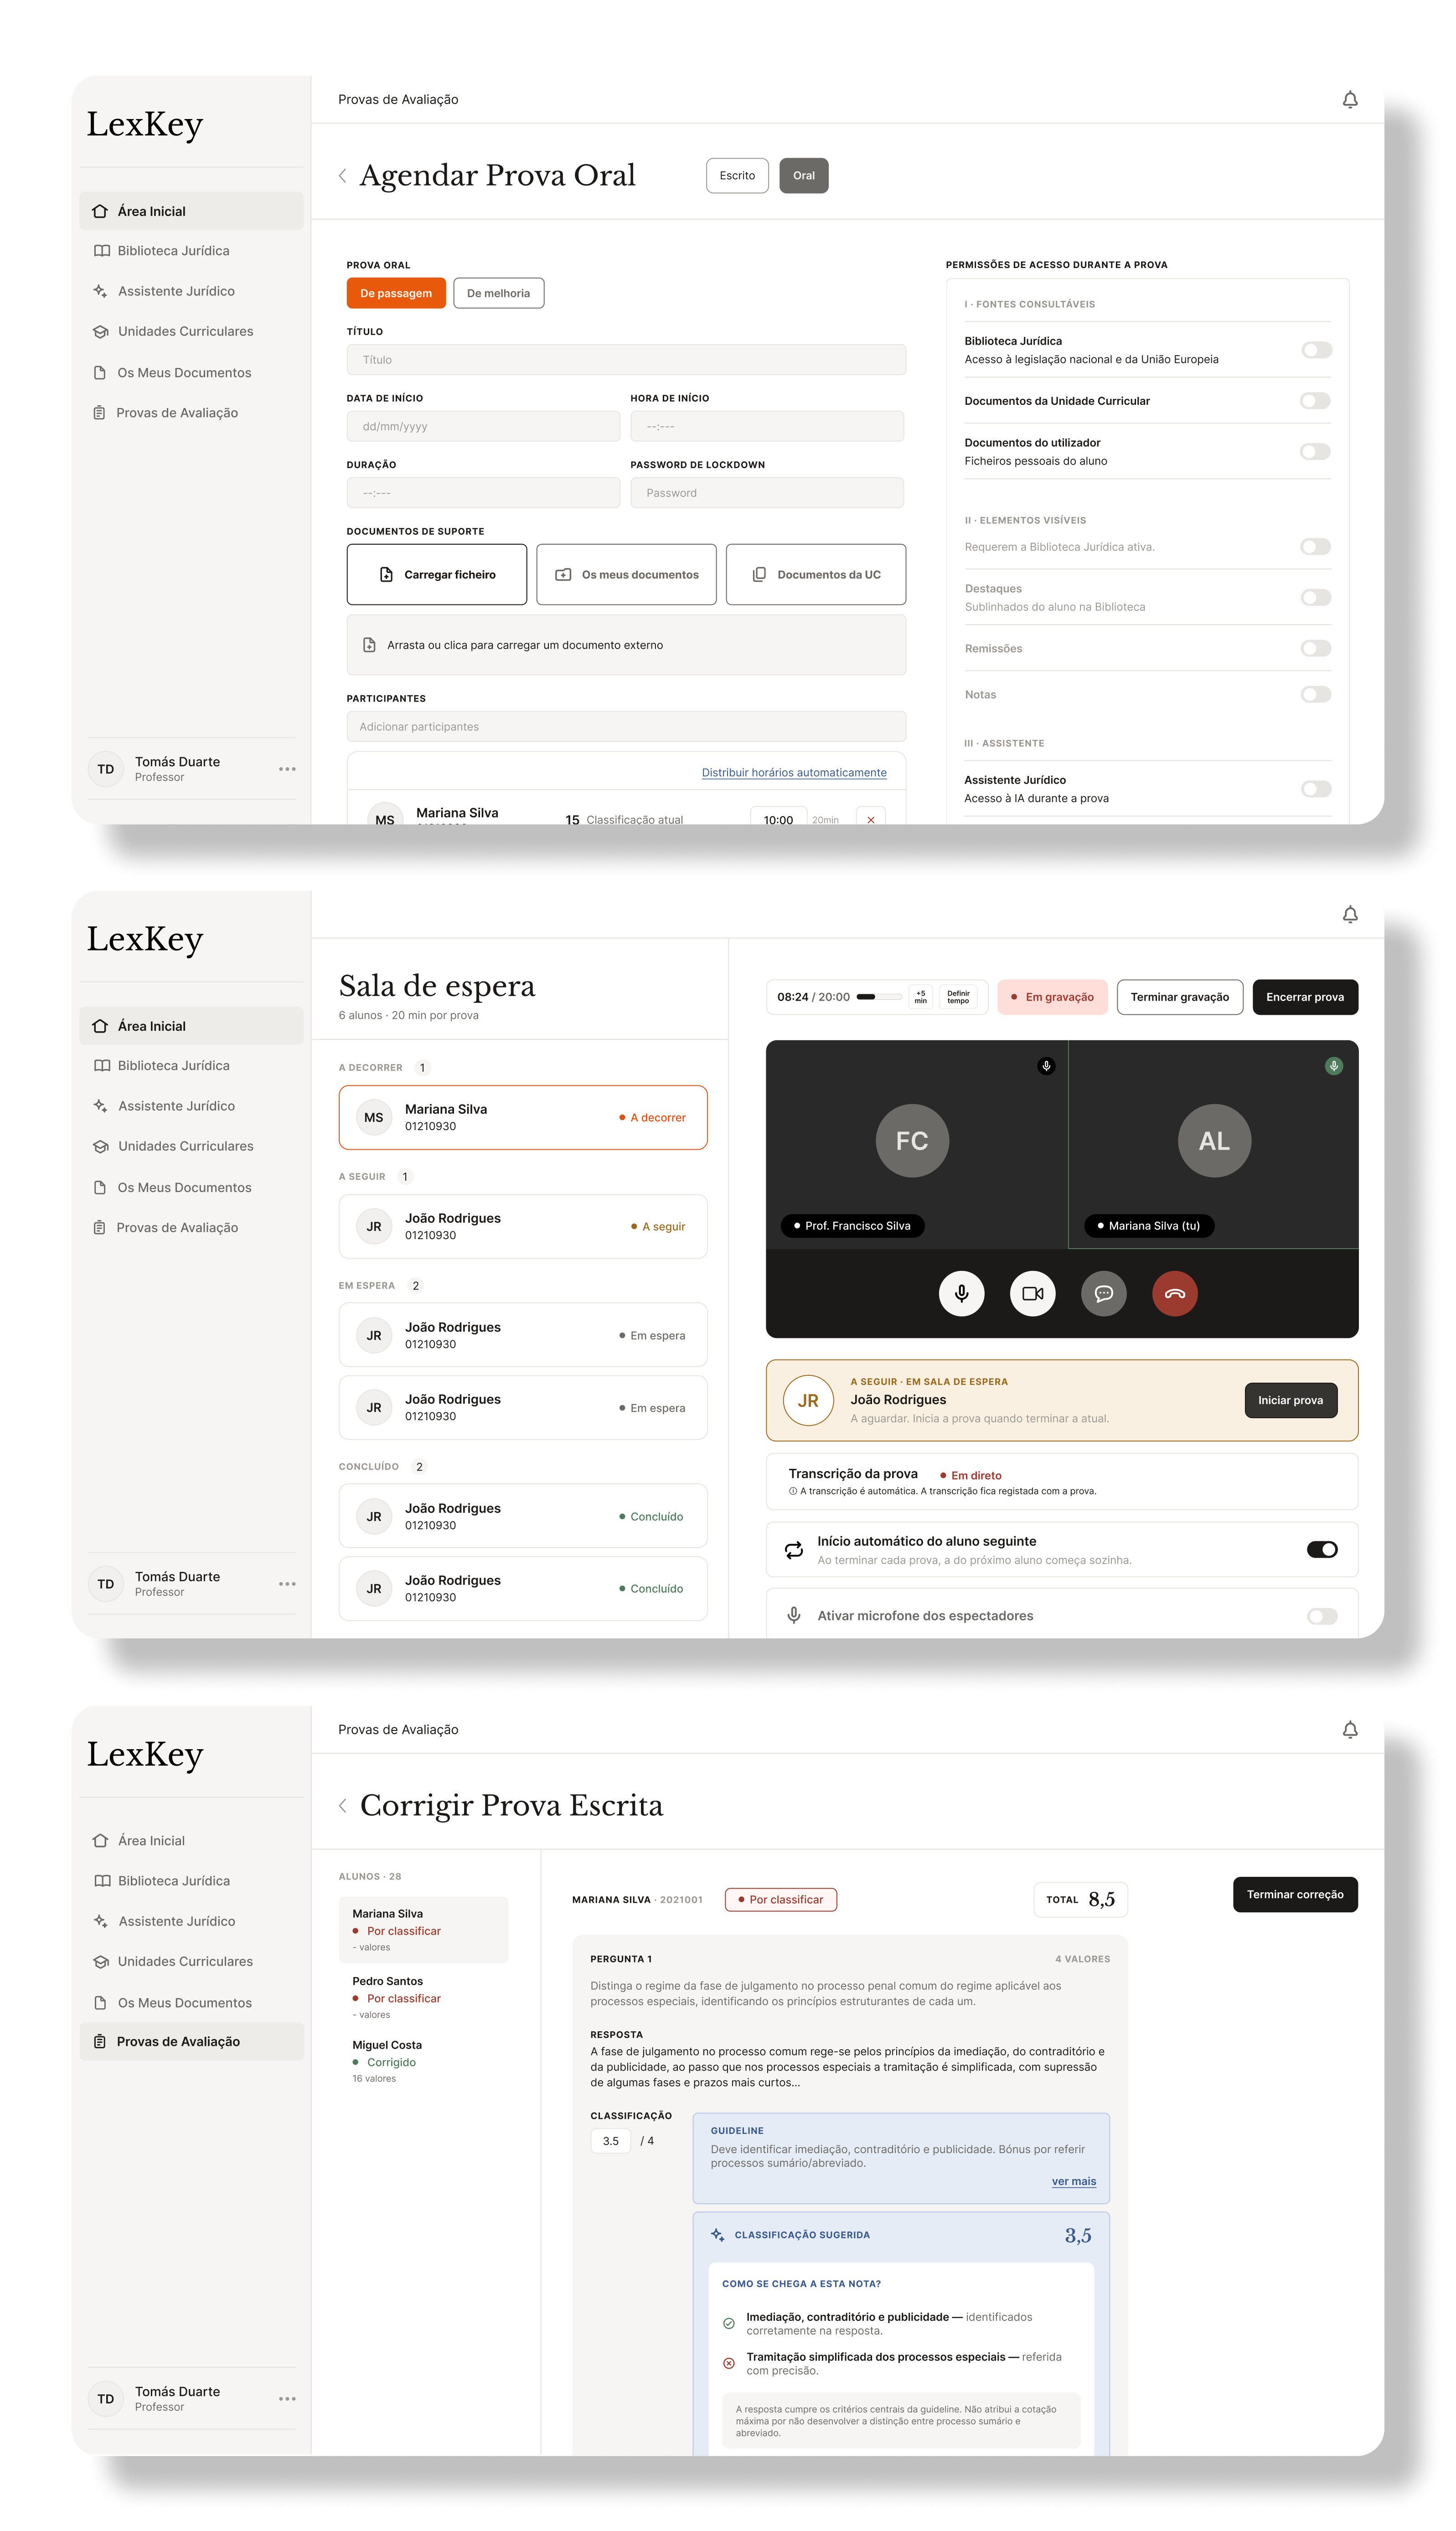
Exams are open by default, closed by choice. Digital exams usually lock everything down. In law that assesses memory, because practice always happens with the law in front of you. The professor defines what stays available, per exam — legal library, course documents, the student's own documents, the AI, even copy-paste, separated by source.
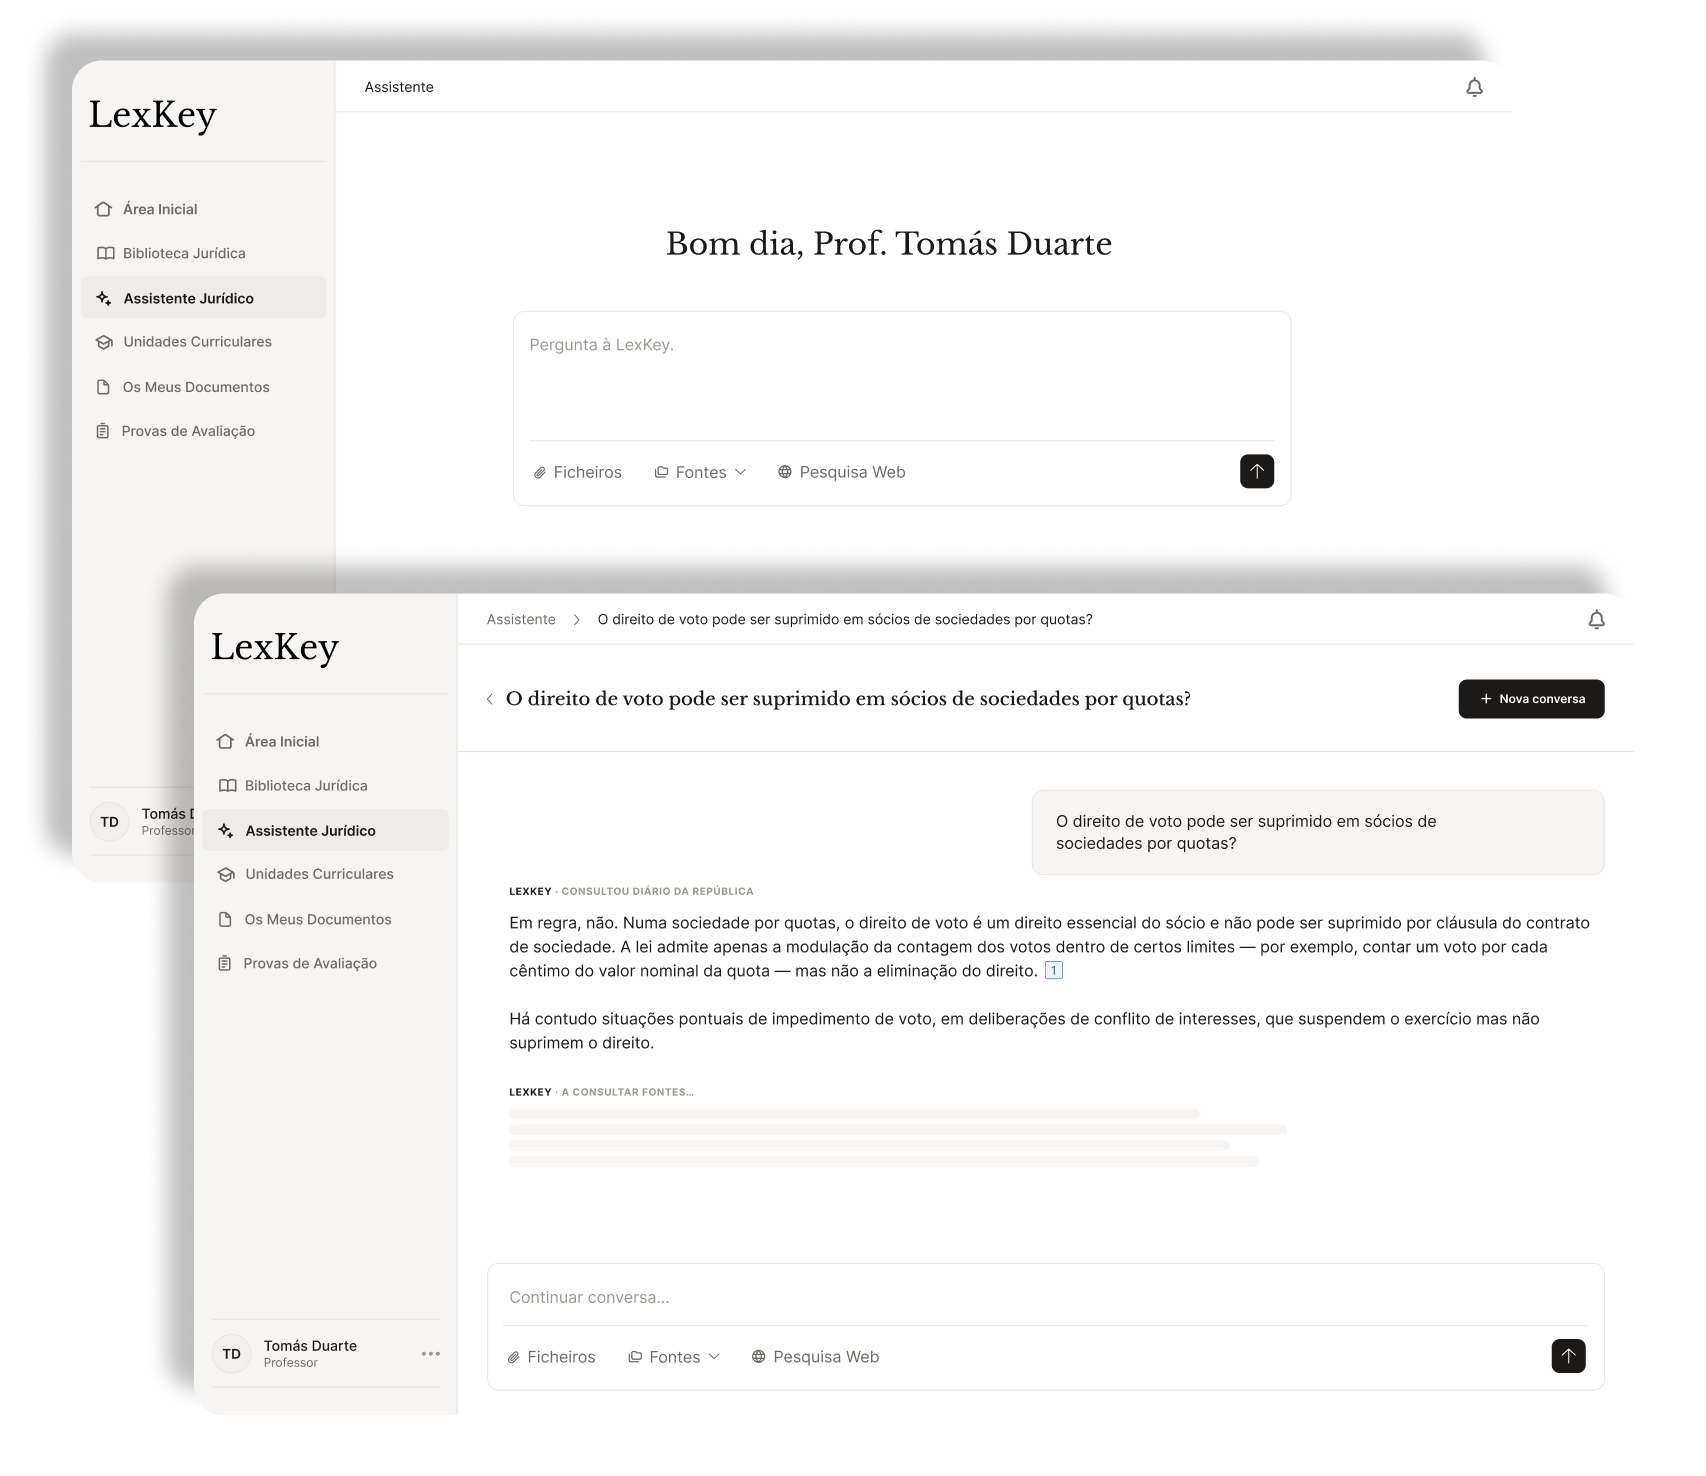
The AI applies the professor's criteria, never its own. The marking guideline is written when the question is created. During grading the professor can request a suggested mark and gets the reasoning criterion by criterion — what the answer met, what it didn't, and why it fell short of full marks. The suggestion is requested. It never appears on its own.
Consistency and transparency as product mechanics, not as policy. Grading can be anonymous, with names revealed only once marks are closed. Extra time for students with accommodations is configured before the exam and applied automatically. These are mechanisms that support fairer assessment. Whether they produce it depends on how institutions use them.
A layer that belongs to the student. The platform is organised by the institution's logic — courses, classes, calendar. That isn't how a law student organises study: they accumulate annotated legislation across years, and what matters rarely stays inside the course it appeared in. So they get their own layer, with documents, folders and tags they define. The curriculum organises teaching. It doesn't have to organise study.

Trade-offs
Risks named during the decision, and what I'd watch in implementation.
Alternative — configure permissions screen by screen.
Decision — reusable groups with dependencies.
What it costs — more complexity upfront.
What I'd monitor — whether a group becomes a dump for exceptions, which would return us to individual configuration by another route.
Alternative — lock everything down during exams.
Decision — the professor configures access per exam.
What it costs — more setup, and two exams in one course can differ.
What I'd monitor — whether professors can build the exam they want without help.
Alternative — let the AI grade autonomously.
Decision — it applies written criteria, on request.
What it costs — criteria must be explicit before the exam, and many people hold them in their head during marking.
What I'd monitor — whether professors recognise the suggestion as theirs.
Alternative — one configurable grading flow.
Decision — separate flows for written and oral.
What it costs — more structural complexity.
What I'd monitor — whether the two flows drift far enough apart to stop sharing anything.
Testing & Metrics
I ran a 30-minute moderated usability test with five people who teach or supervise students in a higher-education context, focused on the Professor role and on the two decisions where the system deliberately asks the user to define the rules before using AI.
1 · Configuring exam access
Task — create an exam where students can use the Legal Library but not their own notes.
Result — 4/5 completed it without help. The dependency model was understood: participants selected what should stay available and treated access as configurable per source rather than one global switch. One participant expected a single setting to control every exam permission, then recovered unprompted after exploring the screen.
2 · Defining the grading criteria
Task — configure the AI's mark suggestion to reflect your own criteria.
Result — 4/5 understood the guideline had to be defined before the AI could be used; one looked for the AI first and found the guideline afterward. What mattered wasn't whether people found the field — it was whether they treated the guideline as part of the assessment definition rather than optional setup.
3 · Reviewing an AI-suggested mark
Task — correct an answer and decide whether you agree with the AI's suggestion.
Result — all five completed it. 3/5 opened the reasoning criterion by criterion before deciding; 2/5 accepted the mark immediately and only checked the reasoning when asked what had supported their decision. Asked do you recognise this mark as your own?, 4/5 said yes — because the reasoning matched the guideline they'd defined. One wanted to see the supporting evidence before feeling comfortable applying it.
This is the counter-metric that matters here: 2 of 5 participants were willing to accept the AI's suggestion before checking how it had been reached. Validation can't depend entirely on the teacher choosing to inspect the reasoning.
What changed because of it
The test supported the decision not to let the AI grade autonomously or surface a score without context. But it exposed an interaction gap: I'd keep the suggestion on request, and make the criterion-by-criterion reasoning more prominent at the moment of decision, rather than secondary detail someone has to choose to open. The principle held — the AI can make the suggestion, but the teacher needs enough information to recognise the decision as their own.
What I'd still instrument
Hypothesis — the group model makes a new institution cheap to stand up.
Test — time-to-first-class on a new tenant.
Metric — hours from account creation to first class configured.
Hypothesis — teacher validation stays real at scale.
Test — compare suggested marks against final marks in production.
Metric — percentage of AI suggestions accepted with zero change. Above roughly 80%, I'd treat validation as compromised and revisit the flow — the same threshold the moderated test already pointed toward.
Neither of these is running yet. The usability test covered comprehension and trust in a moderated setting; it doesn't tell me what happens at volume, unsupervised.
Learnings
I'd bring real professors in earlier. Lawyers were essential for terminology and rules, but knowing a field and using a product every day are different things. The usability test came after the fact, not before interaction patterns were locked — next time I'd run it earlier, while decisions were still cheap to change.
Metrics belong in week one. Not because there's data early, but because writing down how will we know this worked changes the decisions you make next.
A concrete mistake. I put annotation controls under every source, when they only made sense inside the Legal Library. I fixed it, and kept the principle: consistency isn't applying the same pattern everywhere — it's applying it where the product model supports it.
What's still open
The usability test covered comprehension and trust, not real classroom use. Five moderated sessions show people can configure access and recognise a mark as their own — they don't show what happens across a semester, at volume, unsupervised.
The permission model holds in design. Whether it holds in implementation is unproven — the fourth role was absorbed on paper, not in a shipped system.
The oral assessment flow is the least supported by precedent. It's the furthest from patterns that exist elsewhere, and the one I'd expect to change first.
Adoption against an installed LMS is a commercial risk design can only partly address. Better flows don't rewrite a procurement decision.
